Putting it to work · 9 minutes
The layer you own
What to rent, what to run yourself, what to own, and where a person always decides.
David Reynolds · September 2026, updated October 2026
In this piece · 8 sections
In plain terms. Every competitor can get the same models, and they get better and cheaper every few months. So the model shouldn't be where your advantage lives. For each step of the work, choose the model that suits that step: rented, licensed, hosted or run on your own machines. Then own the three things every model plugs into: a connected picture of the business, a register of what's running, and a test set of your own cases. Own those, and changing a model becomes a setting rather than a project.
Most businesses I talk to are being offered the same thing by every vendor, whether they sell advice, insurance, data or software: an agent for intake, an agent for research, an agent for quality checks, each sold separately and each very good at its own task. The pitch is usually true. The trouble is what happens when you buy five of them.
Each one arrives with its own copy of your customers, its own idea of what a good answer looks like and its own log. None of them can see what the others know. Your people end up checking five different outputs against five different pictures of the same customer. And when a better agent comes along next year, whatever the old one learned about your business leaves with it.
If every competitor can buy the same agents, the advantage is in what they're connected to.
Expect to change the model
The models are the part that changes fastest. For the same level of capability, the price fell roughly tenfold a year between 2021 and 2024 (a16z). They're also retired on the vendor's timetable, not yours. OpenAI launched GPT-4.5 in February 2025 and took it out of its developer service that July, pointing everyone at a cheaper successor.
So treat the model as a part you will change. I wouldn't train my own, and I wouldn't fine-tune one before good instructions and the right documents fed to it had been tried and had failed.
The same goes for the agents that come inside the software you already pay for. Use them. They're often the quickest way to show people what's possible. Just don't let them become the place your business's knowledge lives.
Rent, license, host or run
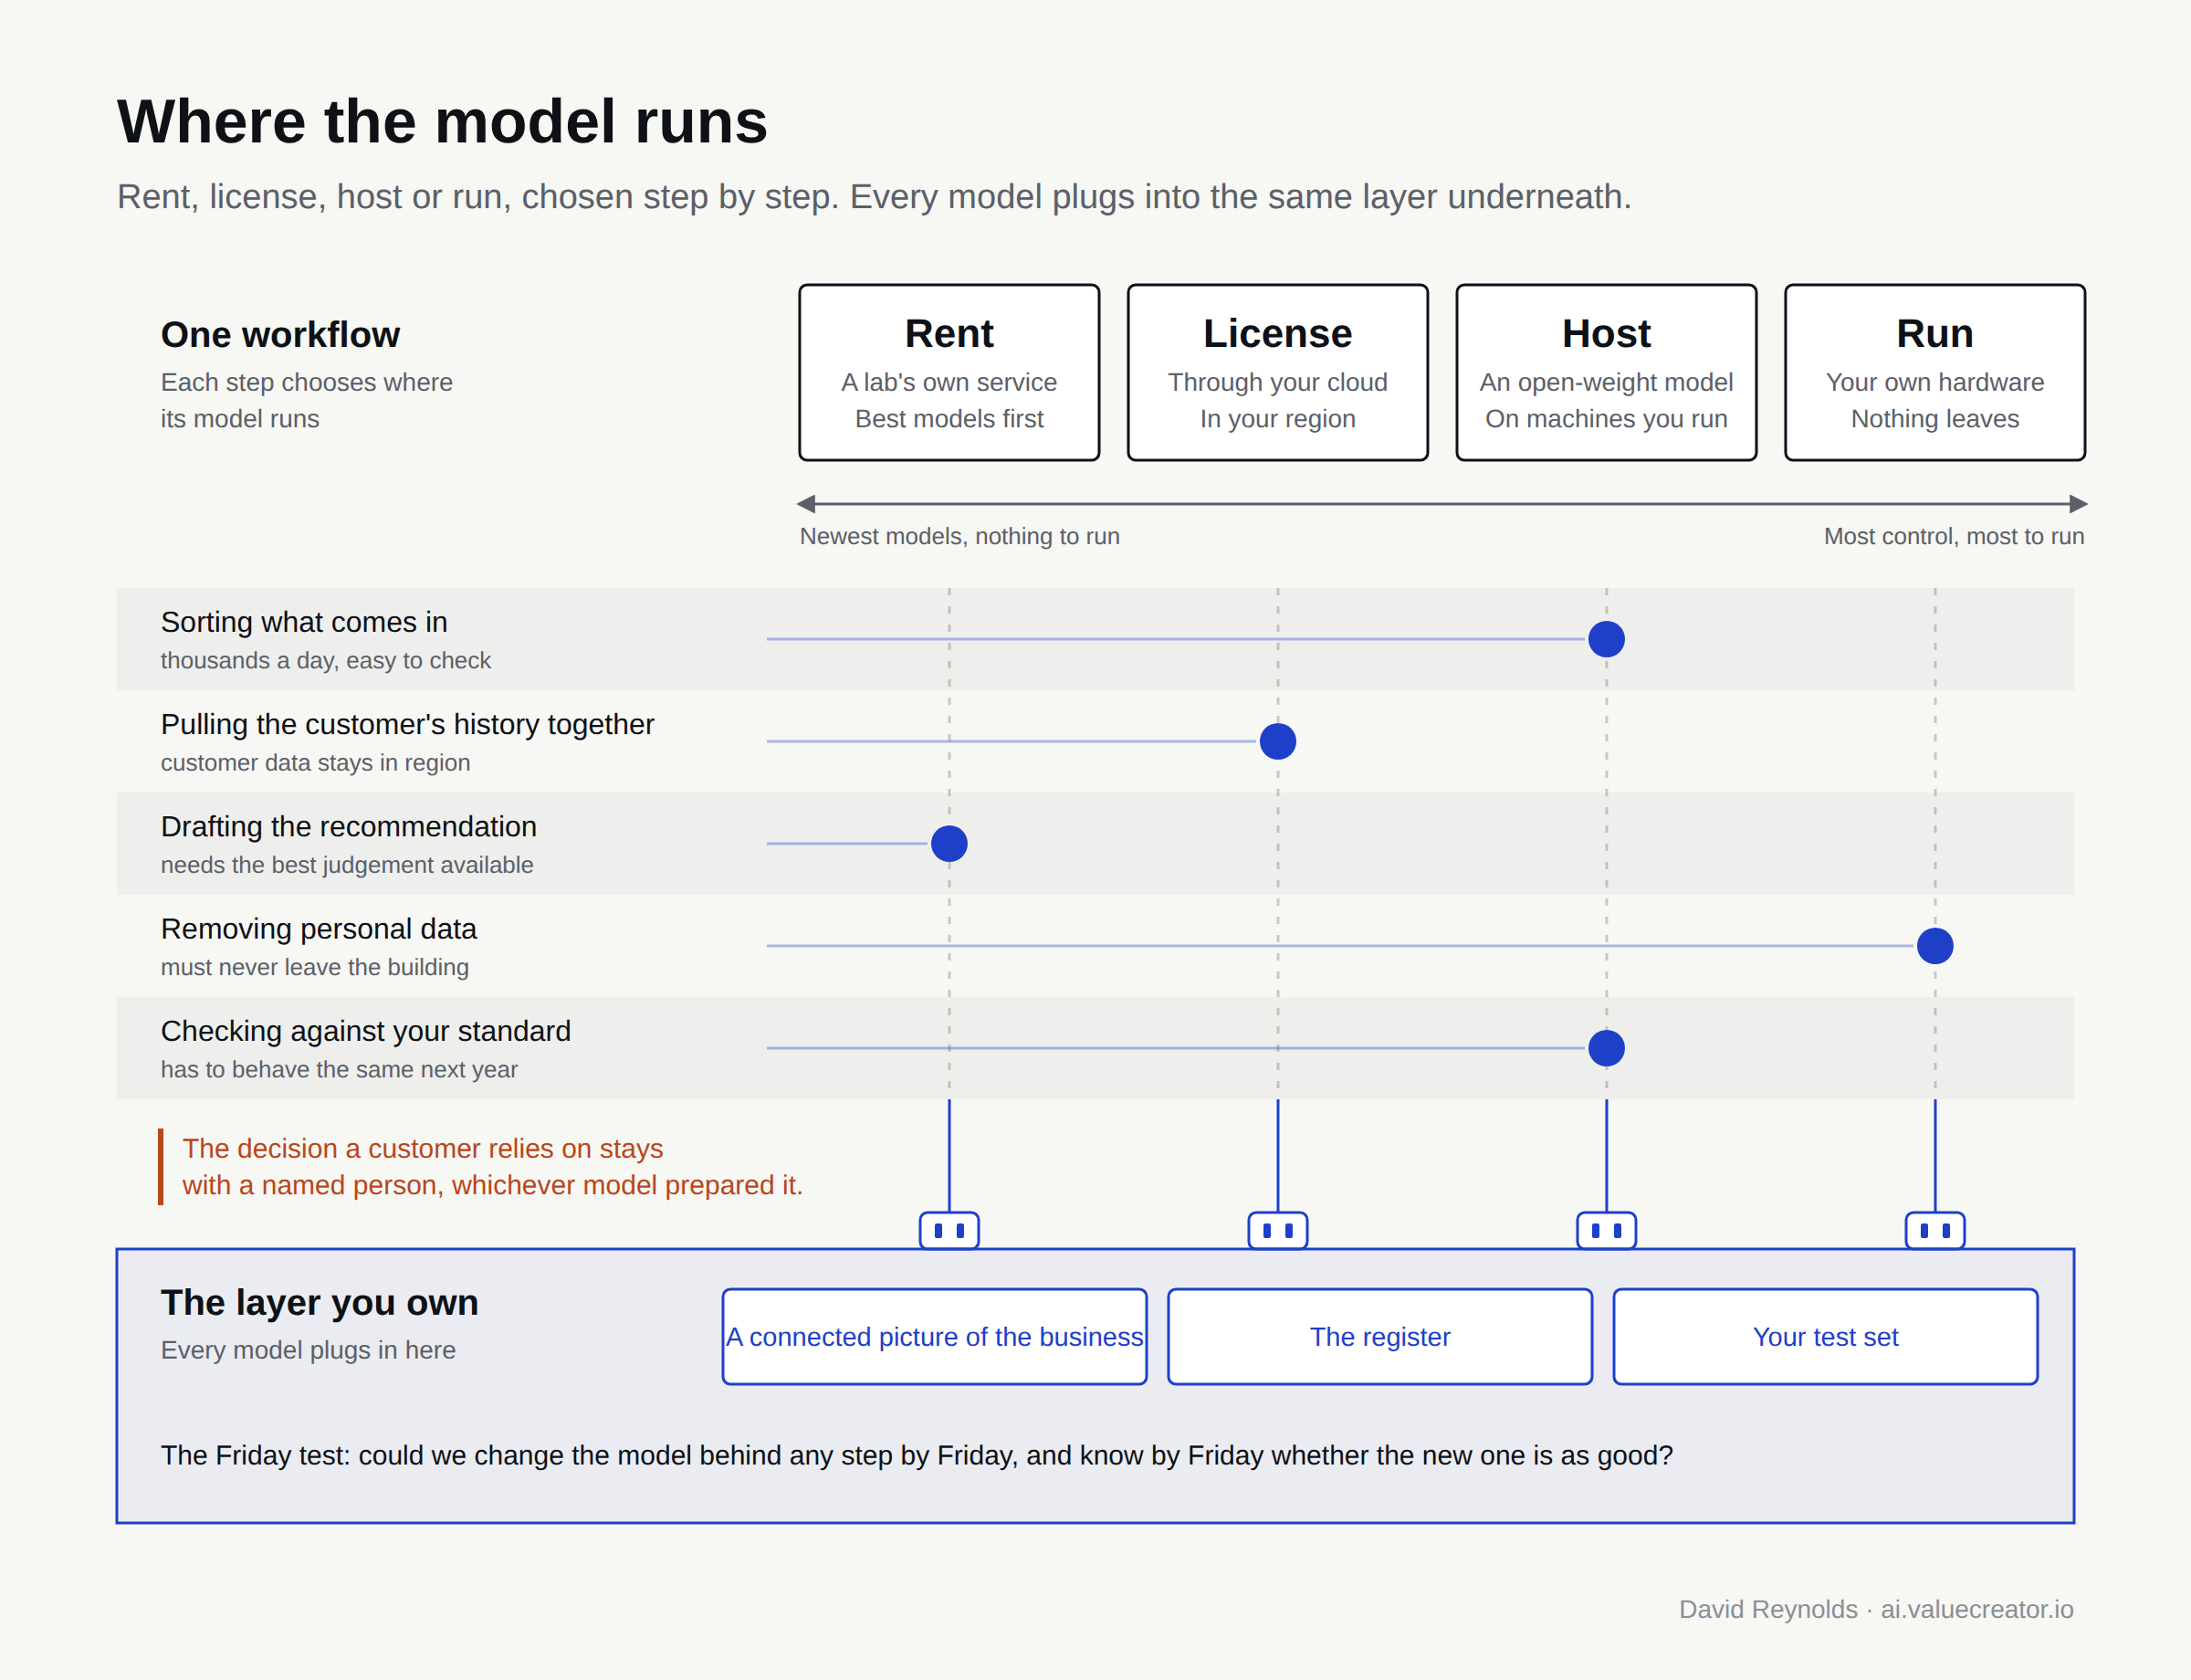
"Rent the models" used to be the whole answer. It now covers four different arrangements, and you don't have to pick one for the whole business.
Rent. Call a lab's own service over the internet. You get the best models first and there's nothing to run. Your data leaves your walls under the vendor's terms, and versions change and retire on their schedule.
License. Many of the same leading models, bought through the cloud provider you already use, under your existing contract and in the region you choose. You're still on the lab's release cycle.
Host. An open-weight model, one whose trained model file is published for anyone to download and run, on cloud machines you control. Nothing leaves, and you decide when the version changes. You pay for the machines rather than for each use. For the hardest judgement it is often a step behind the best rented models; for extracting, classifying and matching it is usually more than enough. When OpenAI published its first open-weight models since 2019, in August 2025, the smaller one could run on a computer with 16GB of memory.
Run. The same kind of model on hardware you own, sometimes with no connection to the outside at all, for the work that must never leave the building.
These sit side by side. In December 2025 HSBC signed a multi-year deal with Mistral that included models running on the bank's own systems. HSBC could rent any model it wanted. It still chose to run some models itself.
The choice is made one step at a time, because not every step deserves the most capable model:
| If the step | Lean towards |
|---|---|
| needs the best judgement available, and runs a few times a day | Rent or license the best model |
| uses data that mustn't leave a country or a customer's control | License in the right region, or host |
| runs thousands of times a day and can be checked | Host a small model, or the cheapest that passes |
| must work with nothing leaving the building | Run it on your own hardware |
| has to behave identically for an auditor next year | Host, so you decide when the version changes |
The model is a plug; the layer is the socket
Switching is easier than it has ever been. Most model providers now accept requests in much the same shape, so the code that calls a model barely changes between them, though the instructions often need retuning, which is what the test set is for. A gateway, one switchboard that every model request passes through, can send each step to a different provider and record which one answered. Agents connect to tools and data through open standards that no single vendor owns (Earned autonomy has the detail).
That only helps if everything that makes the answer yours sits outside the model. Keep the instructions in your own version control, the knowledge in your own picture of the business, and the standard of a good answer in your own test set. If those live inside a vendor's product, every switch is a rebuild.
There's a simple test for each step: could we change the model behind it by Friday, and know by Friday whether the new one is as good? If the answer is no, you're renting more than the model.
Own the layer underneath
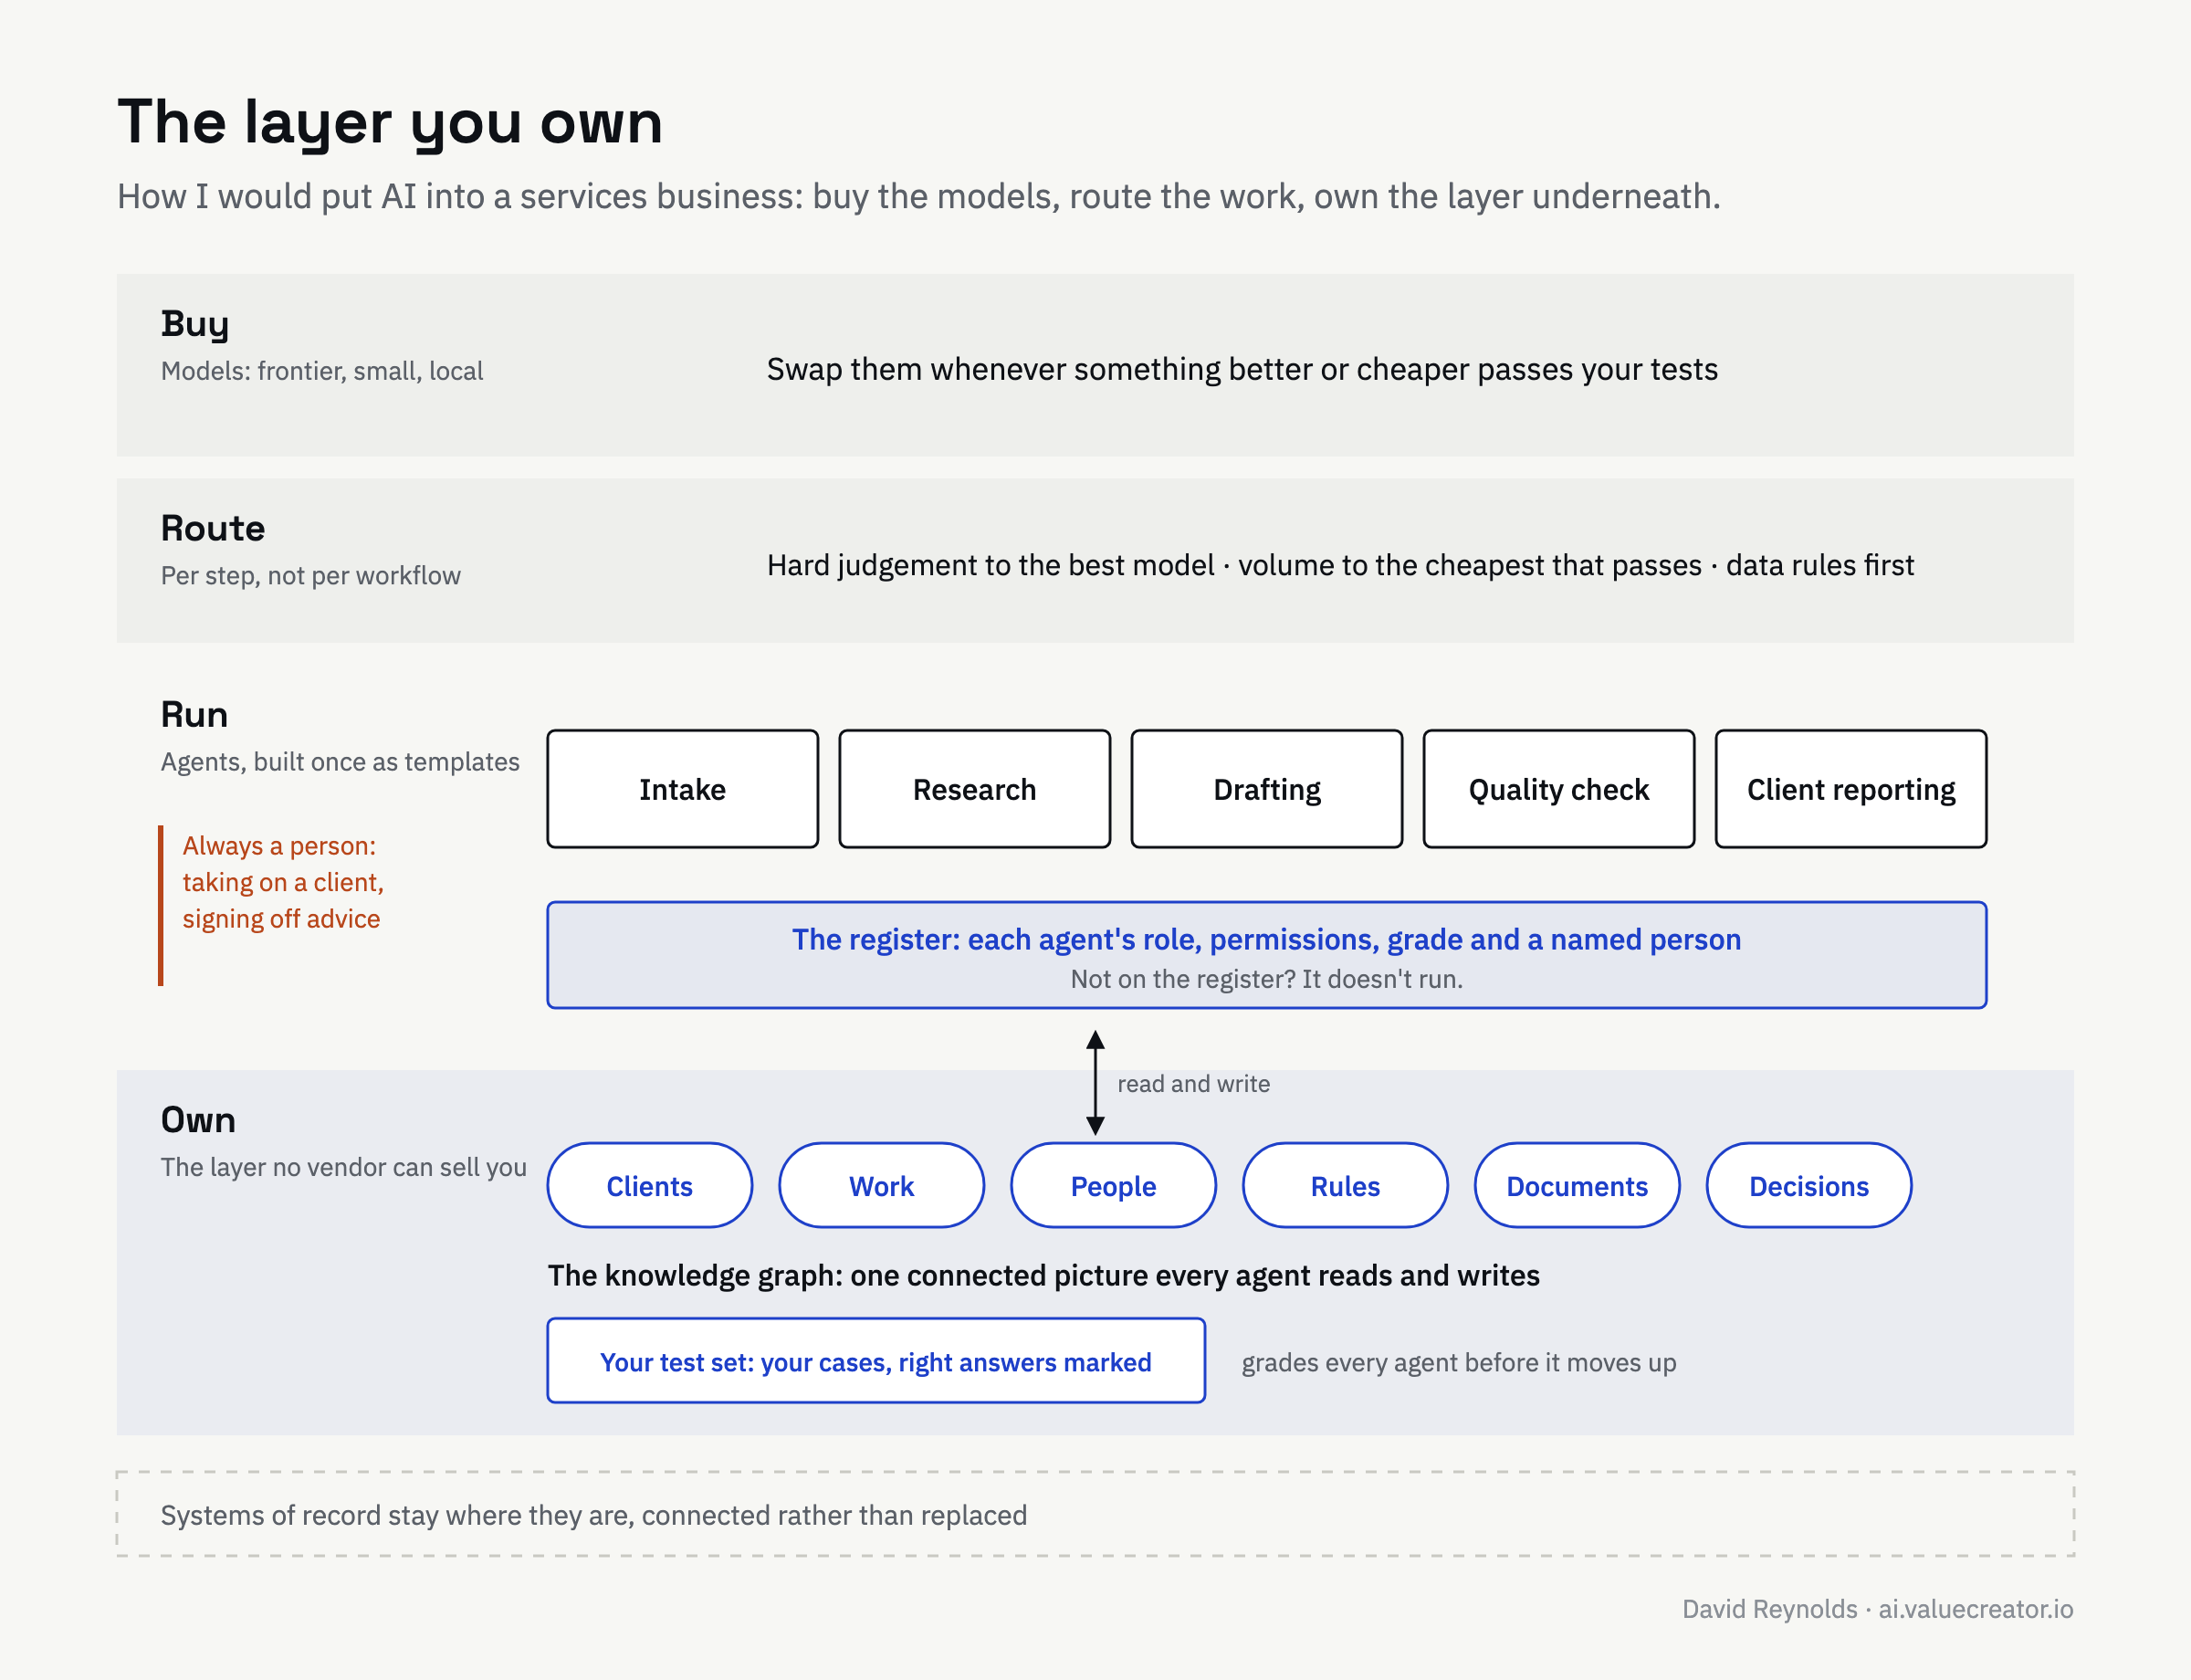
This is the part I'd build and keep, and it's smaller than people expect. It has three pieces.
A connected picture of the business. Your data probably already sits in a data warehouse. That stores it, but nothing links a customer to their history, the people who work with them, the rules that apply, the documents that matter and the decisions taken, and by whom. That linked picture is what agents need.
I call it a knowledge graph, but the name matters less than two rules. Build only what the first workflow needs; don't fund a grand data model. And store decisions alongside facts, because an agent can't be taught a decision nobody wrote down, and that record gets more valuable every time it's used. Because every agent reads and writes the same picture, they stay consistent with each other: the intake agent and the quality-check agent agree on who the customer is because they're reading the same record.
A register. One page per agent: what it does, what it may read and change, which model it uses and where that model runs, the grade of autonomy it has earned, and the named person who answers for it. If it isn't on the register, it doesn't run. Earned autonomy sets out what goes on the page and how grades are earned.
A test set. Real cases from your own work, with the right answer marked by people qualified to judge it, and never shared with the vendors whose models it tests. Every change to an agent, a model or a prompt runs against it before it goes near a customer. It's what lets you pass the Friday test, and it's a real answer when someone asks how you know the thing works. Earned autonomy covers how to build one.
Always a person
Some decisions stay with a named person at every stage: taking on a new customer, signing off advice, approving a claim or a loan, anything a customer will rely on without checking it themselves. The machine prepares; the person decides. In a services business, clients are paying for someone to stand behind the answer, and the same is true of a lender's decision, an insurer's settlement or a number a data business publishes.
Build once, configure for each market
In a business that runs the same work in several countries or teams, the temptation is to build a version for each. Don't. Build each workflow agent once. Put the differences between markets in the knowledge graph as configuration, so two markets run the same agent reading different rules. That includes which models a market may use: where the customer sits can decide where the model runs, so that rule is written into the routing rather than left in a policy document. Then let each deployment earn its own autonomy. The same agent can be acting on its own in one market while it's still only recommending in another, because the evidence in each is different.
What it's worth
The graph, the register and the test set are assets. They survive a change of model, a change of vendor, a move from renting to running your own, and the next acquisition, because the next business you buy plugs into the same picture rather than starting again. They're what a buyer's diligence team can actually read. And they let you show customers evidence that the work is right, which is usually the moment they'll pay more for it.
Own the three things above and source the rest well.
Where to start
One workflow, one team, end to end. If you can bring one customer's history together from the systems it's scattered across inside eight weeks, the graph is real. Write down, for each step, which model it uses, where that model runs and why, and run the Friday test on one of them. Put one agent on the register, running alongside the team on live work with nothing it produces sent out, and write down the criteria it has to meet before it's allowed to do more. Measure before and after. Then decide, in the room, whether to carry on.
Test it against your own business: Where you are →